Selective visual inference with observable decisions.
Agentic Vision explores a simple idea: visual intelligence does not have to treat every frame as a completely new problem.
A lightweight scene descriptor identifies when the observed environment remains semantically stable and when a new interpretation is warranted. When the descriptor matches, the previous interpretation can be reused. When the scene changes materially, perception can be refreshed.
The result is a measurable tradeoff between inference cost and perceptual sensitivity — with the decision itself preserved as part of the system’s evidence.
From agentic simulation to real-world perception
The architecture originated in an agentic DOOM environment, where thousands of compiled agents interacted with a live game through a Model Context Protocol gateway. Broker agents observed different aspects of the scene — entities, motion, zones, and HUD state — and invoked vision selectively as those observations changed.
Agentic Vision carries that architecture into real-world imagery.
Road footage extends the architecture into a setting where perception itself is uncertain, allowing different scene descriptors to be evaluated under real-world visual variation. Robot arms take it one step further, to perception that a physical action depends on.
The game build is still running, if you want to see the architecture in its original habitat: agentarena.ca.
Measured selective perception
Across 1,712 contiguous dashcam frames sampled at 5 Hz, progressively richer scene descriptors produced a clear engineering tradeoff.
Scene descriptor
Model calls skipped
Material changes hidden
Class counts
43.6%
28.5%
+ spatial band
37.1%
23.5%
+ spatial band + scale
22.1%
9.1%
A class-count descriptor skipped 43.6% of candidate model calls. Adding spatial and scale information reduced reuse, and reduced the material changes requiring refreshed perception from 28.5% to 9.1%.
The important result is not a single optimum. It is that the tradeoff is measurable.
Scene representation can therefore become an explicit engineering parameter: richer descriptors spend more computation distinguishing states; simpler descriptors maximize reuse.
The trace shows a class-count descriptor reusing the previous interpretation while the scene develops around a vulnerable road user at the curb — illustrating why descriptor richness matters. Rendered from the same trace the measurement emits, so the illustration cannot diverge from the table.
Independent validation
A second perception channel provides an independent view of the same frames.
This captures changes that may not be represented by the detector defining the primary scene state. Cross-detector evaluation therefore provides a stronger measurement of selective perception, and makes disagreement between perception channels observable.
Scene descriptor
Hidden, single channel
Hidden, cross-detector
Class counts
21.5%
28.5%
+ spatial band
15.5%
23.5%
+ spatial band + scale
1.0%
9.1%
In this run, the two channels disagreed about the presence of vulnerable road users on 9.5% of frames.
That disagreement is useful evidence. Instead of disappearing inside the perception pipeline, it becomes something the system can measure, label, and reason about.
Real drives, two cars
The same measurement, at scale: 236,130 frames at 5 Hz from 94 drives of two cars in comma2k19, a public set of commuting drives, graded by the independent detector.
On the 84 drives with complete recordings
Difference
95% interval
Content-triggered refresh against a timer, at the same share of skipped model calls
−2.01 pts
−2.70 to −1.31
The same, on the chunk held out when the analysis was fixed
−3.27 pts
−4.10 to −1.96
Negative means fewer material scene changes hidden behind reused perception. The analysis was fixed in writing before the last chunk’s results existed, and intervals come from resampling whole drives within each car. The earlier dashcam study reproduces exactly on the same engine: 5,136 of 5,136 decisions.
Both perception channels are detectors, so “material change” is what the independent one reports, not ground truth.
A live stack
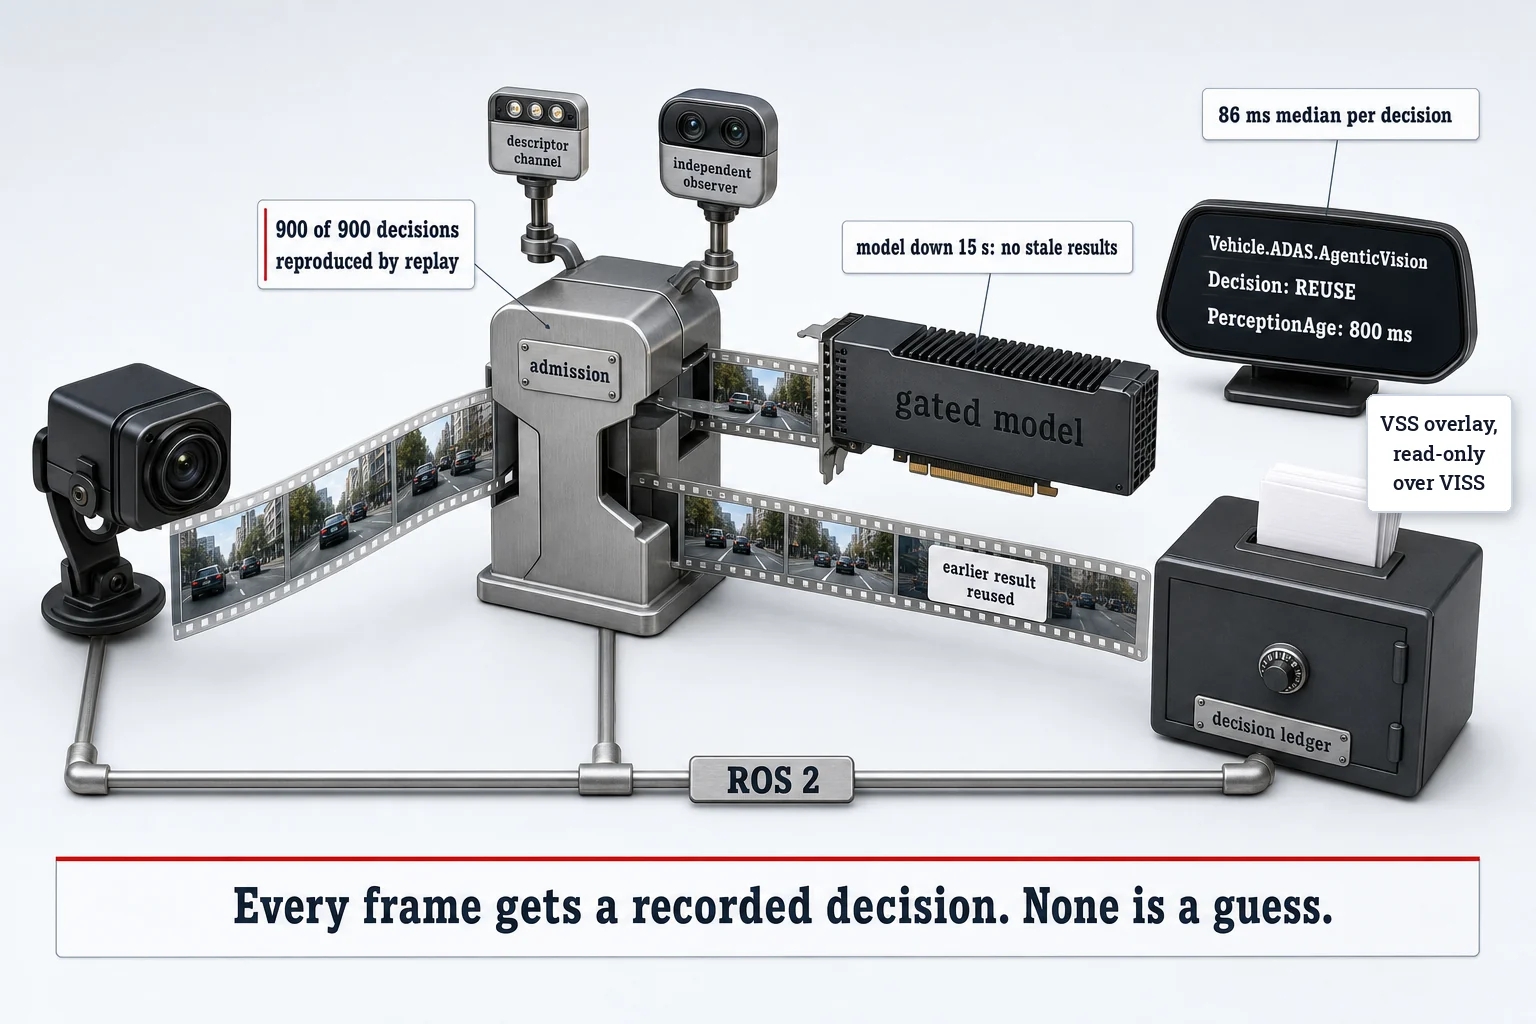
The decision layer now runs live on the interfaces a vehicle integration uses. A recorded drive plays through ROS 2 in real time. A ROS 2 node decides every frame. The gated model runs on a GPU only for the frames sent to it. A detector of a different family runs alongside as an independent observer. Each decision is published on ROS 2 and as a read-only overlay in the COVESA Vehicle Signal Specification, read over VISS through an Eclipse KUKSA broker.
The stack as built, drawn as objects. The three figures on it are measured.
Checked over three minutes of driving (900 frames):
Replaying the node’s recorded inputs reproduces its decision on 900 of 900 frames.
Its detector output matches the offline trace, frame for frame.
Four runs make the same decision on every frame.
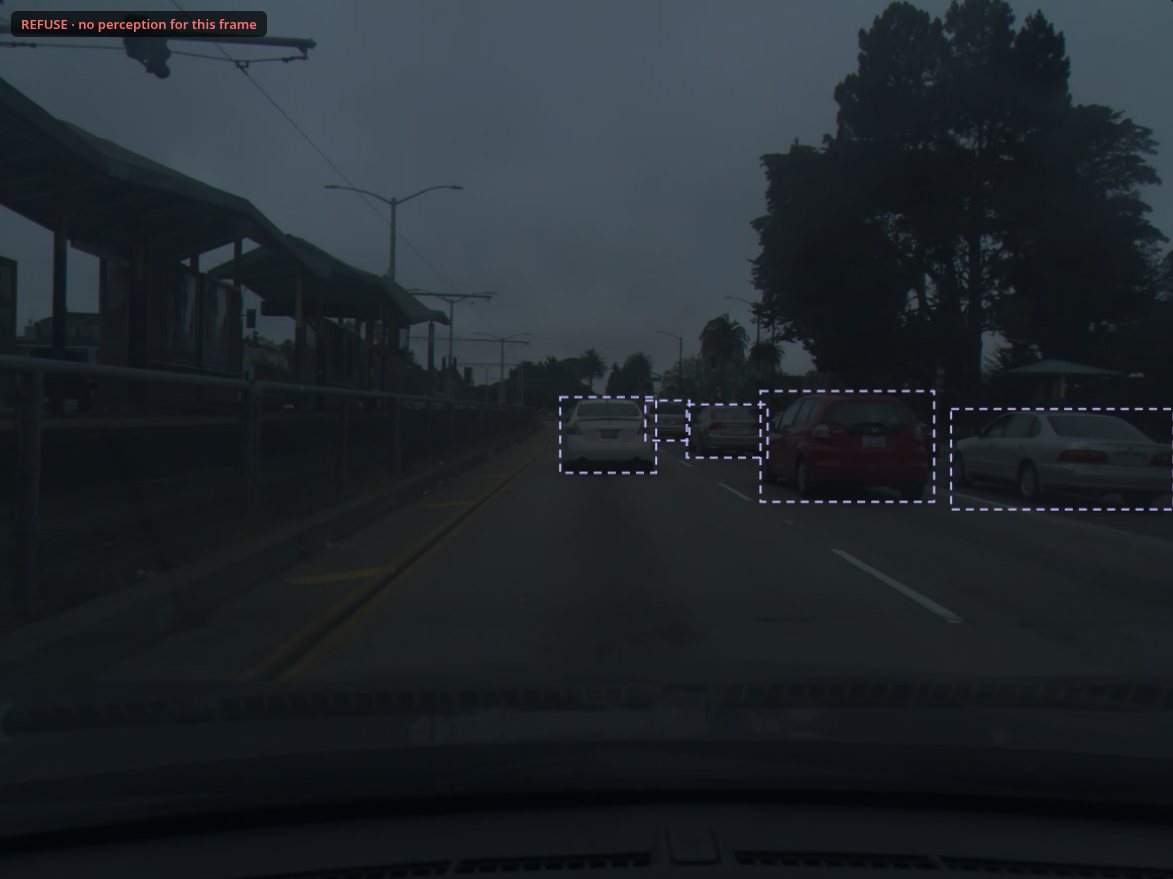
With the model service down for 15 s, the 75 affected frames report no perception rather than a stale result, and the overlay reads not-available rather than its last value.
The overlay is read-only: the broker refuses a write to it.
Median 86 ms from frame arrival to decision, inside the 200 ms frame period.
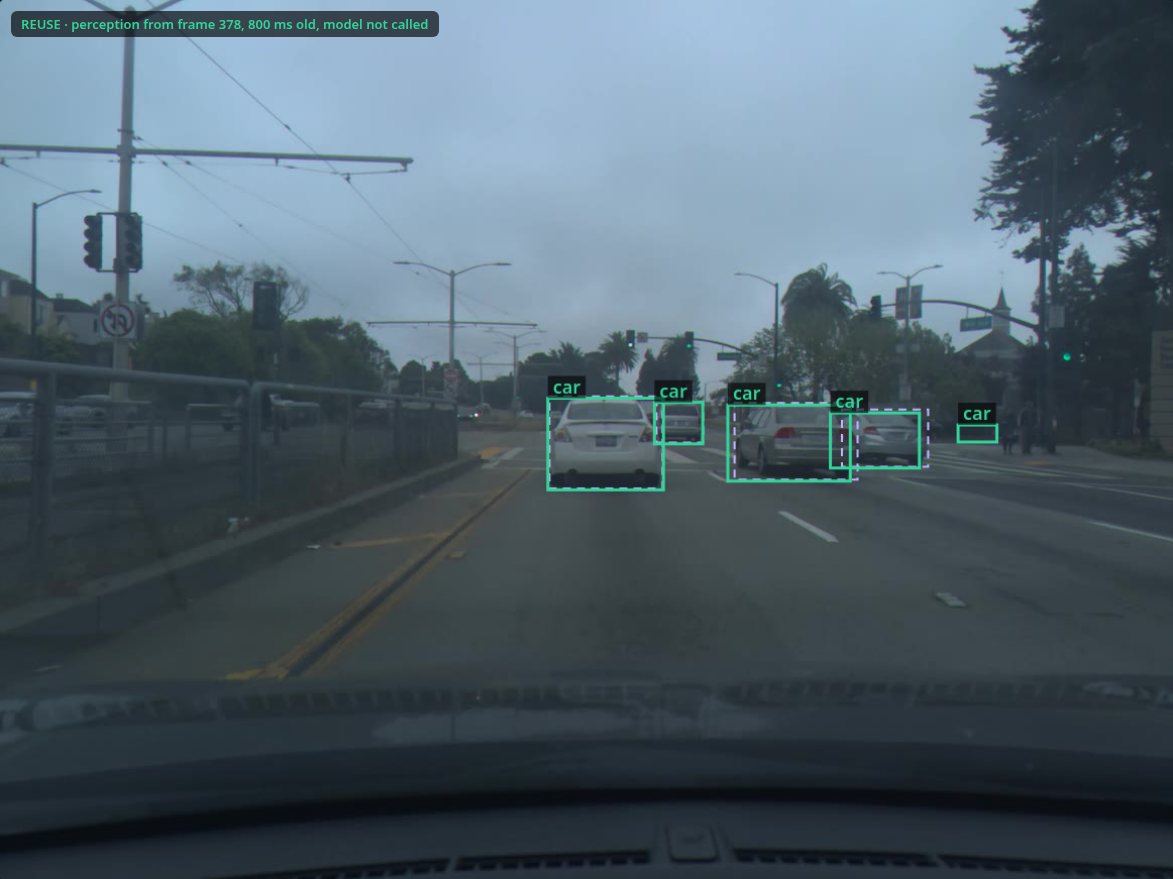
The live view. Left: a frame served by the perception of a frame 800 ms earlier, with no model call. Right: a frame during the outage, with no perception reported; the dashed boxes are the independent observer’s.
Robot arms
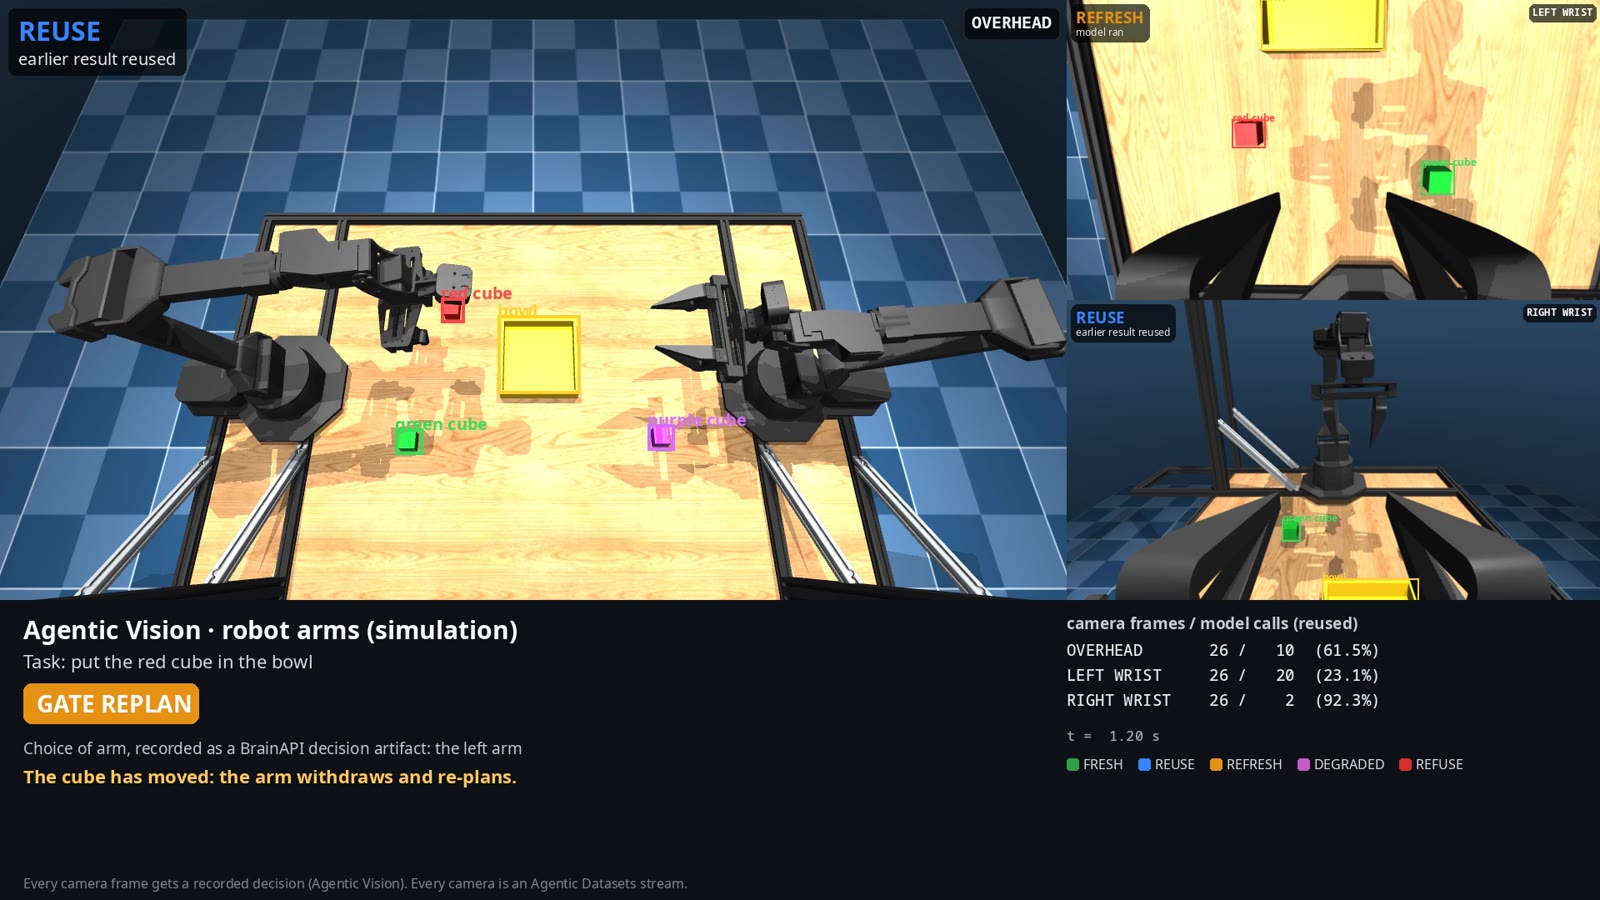
The same decision layer, on a robot. Every frame from every camera gets a recorded decision: run the model, reuse an earlier result, or report no perception. The arm acts only on perception that was admitted, and a gate between perception and motion answers go, hold or re-plan.
The test runs in simulation, on the MuJoCo Menagerie model of ALOHA, a two-arm research robot, with an overhead camera and a camera on each wrist. Each arm puts cubes in a bowl. While an arm reaches, a hand moves its cube 7 cm.
Cubes placed in the bowl
Gate on
Gate off
Seed 0, a hand moves each of three cubes mid-reach
3 of 3
0 of 3
Seeds 1–5, the same disturbance
13 of 15
0 of 15
Seeds 1–5, nothing moved
15 of 15
not run
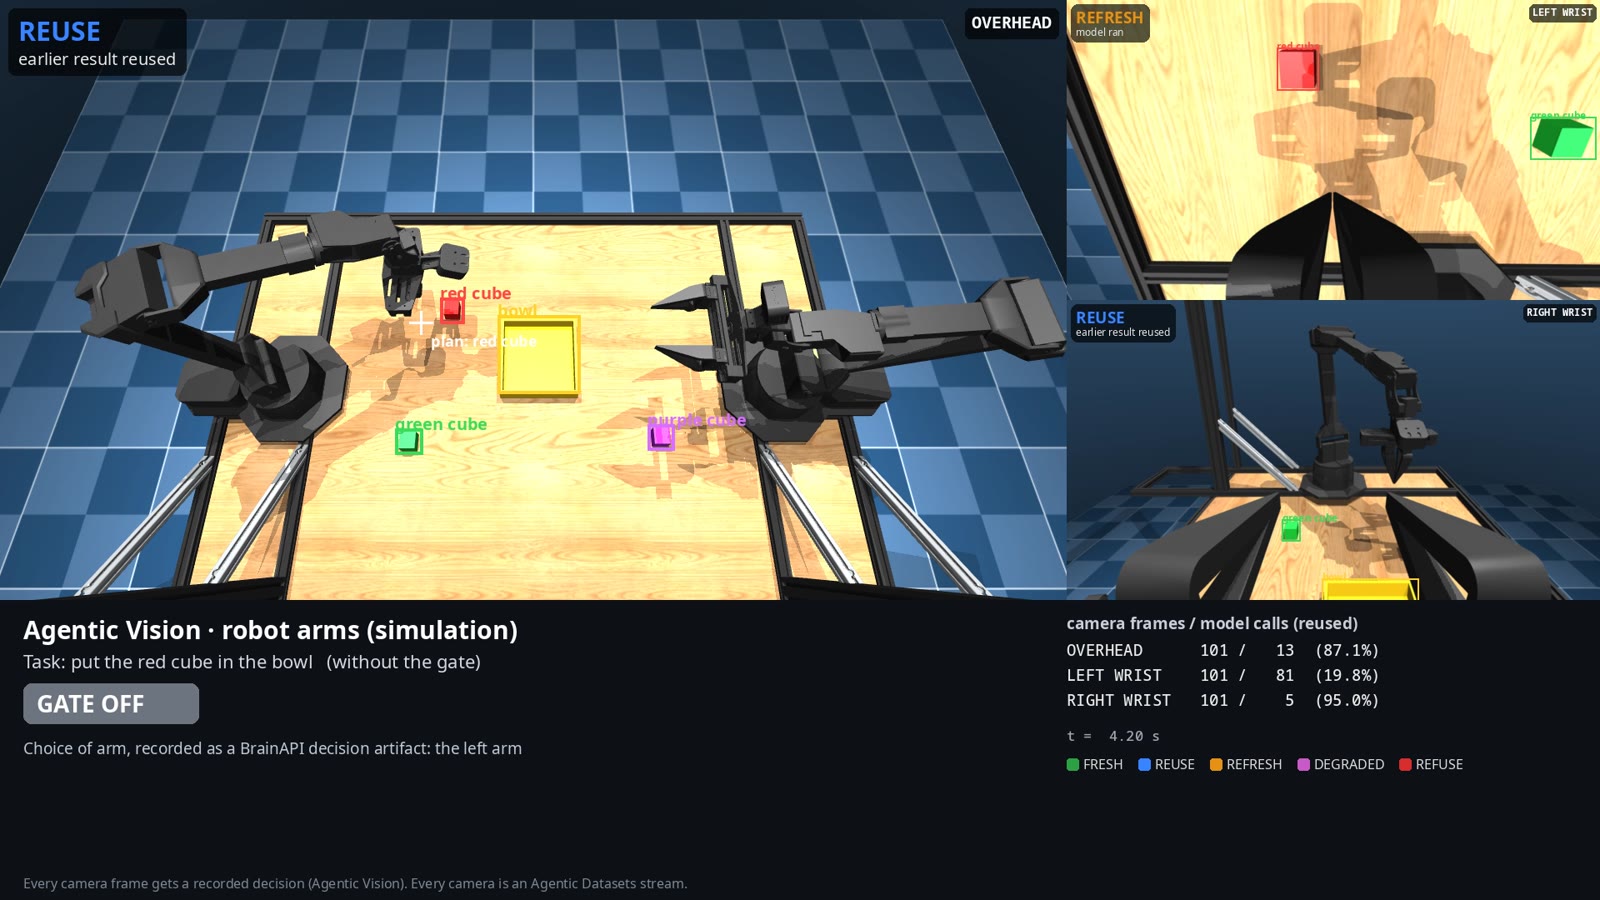
Without the gate, every grasp closed where the cube had been. With it, the arm noticed the move, withdrew, and picked the cube where it was; the two cubes it did not place, it held rather than grasp. With nothing moved, the gate never asked for a re-plan. The arm on its own, picking from the simulator’s true positions, placed 30 of 30 cubes over seeds 0–9.
Over seeds 1–5 with the gate, 41 to 61% of each camera’s frames reused an admitted earlier result instead of running the model.
Seed 0, the same hand in both runs. Top: without the gate, the arm reaches for the planned position (the cross) while its wrist camera shows the cube beside it. Bottom: with the gate, the arm notices the move and the gate answers re-plan. Each camera shows its decision state; boxes are admitted perception only.
Recorded footage of real arms
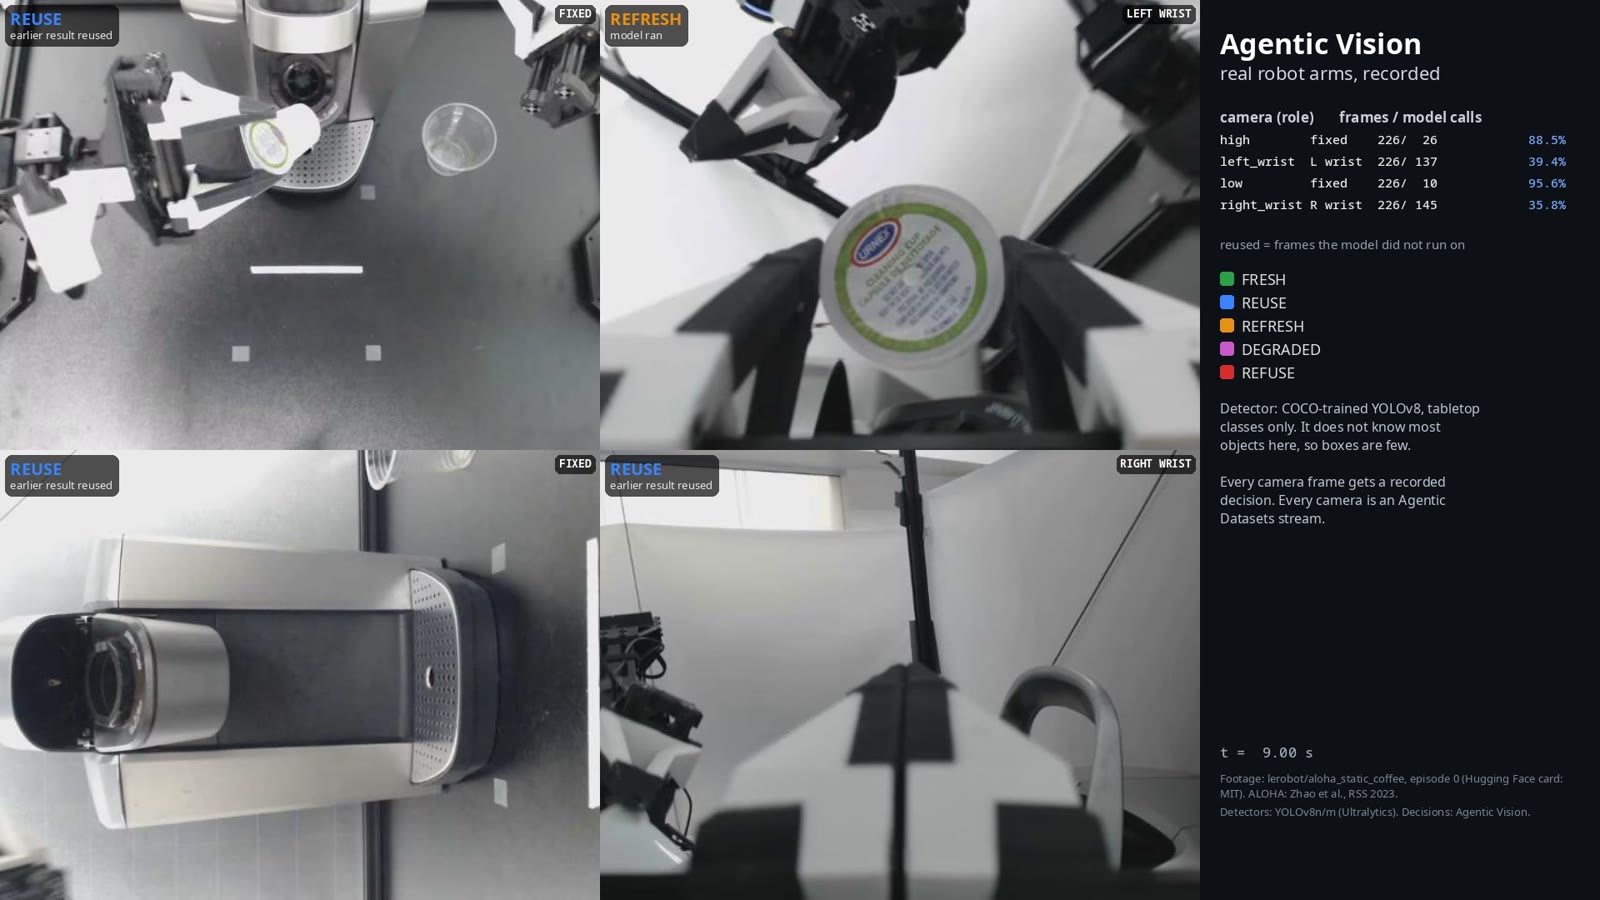
The same per-frame decisions over a recorded episode of a real ALOHA making coffee (lerobot/aloha_static_coffee, episode 0): four cameras, every frame decided. In the first 14 seconds the model ran on 20% of the overhead camera’s frames, 4% of the low camera’s, and 57 to 59% of the two wrist cameras’.
The detector is a COCO-trained YOLOv8 restricted to tabletop classes. It recognizes few objects in this scene, so the footage shows the decisions, not the detections.
Nine seconds into the episode: each camera’s decision state, and the running count of frames and model calls.
The stack
The admission engine from the car work, in Rust: one recorded decision per camera frame.
The choice of arm is recorded as a BrainAPI decision artifact.
MuJoCo with mink inverse kinematics for the arms; YOLOv8 on CUDA for the recorded footage.
These are simulation results and one recorded episode replayed. No physical robot has run this.
Agentic Datasets for perception
A scene fingerprint is a descriptor. Reusing an existing interpretation is an admission decision made against that descriptor.
Agentic Vision applies the Agentic Datasets model to continuously arriving perception:
Sources declare what evidence they provide; experiments declare what evidence they require; admission is evaluated before execution.
Source
Temporal experiment
Descriptor collisions
Live imagery
Academic stills
requires track identity
admitted
requires live pixels
Academic tracks
admitted
admitted
requires live pixels
Dashcam capture
admitted (derived)
admitted (derived)
admitted
Simulation capture
admitted
admitted
admitted
A temporal experiment requiring track identity is admitted only for a source capable of supplying tracks. Derived channels remain explicitly identified as derived. Live-image experiments require pixels.
This makes the relationship between data, capability, and execution explicit.
Selective inference therefore becomes more than an optimization: it becomes an observable, measurable, and governable part of the perception architecture.
Agentic Vision is an independent technical project initiated and maintained by Alexander Chernov. It is an application of Agentic Datasets to visual perception.
The current release measures the selective-inference decision layer on 1,712 dashcam frames and on 236,130 frames of real drives from two cars, each with two independently derived perception channels, and runs the same layer live on ROS 2 and the Vehicle Signal Specification. The same layer also decides every camera frame of a simulated two-arm robot and of a recorded episode of a real one.
The replay measurements invoke no vision model: they determine when a call would occur and what deferring it costs. The live stack and the robot runs do call one. Nothing here has been validated for use in a vehicle or on a physical robot.